PointStream Interactive Inspector
Teleoperation tracking (mean of all three demo clips)
RTMPose-L on the 1080p reference is GT. The same model is run on each reconstruction. Detection is GT-hand recall; unmatched GT hands count as PCK misses. MediaPipe-on-pixels is no longer the judge.
| Metric | PS 240p | AV1 240p | PS 360p | AV1 360p | PS 540p | AV1 540p | PS 1080p | AV1 1080p |
|---|---|---|---|---|---|---|---|---|
| Joint error MPJPE (px, ↓) | 77.5 | 81.1 | 65.8 | 74.2 | 64.6 | 62.8 | 74.3 | 48.8 |
| Hands recovered vs GT (%, ↑) | 50.3 | 51.8 | 53.3 | 57.0 | 53.1 | 66.1 | 56.8 | 72.7 |
| Bitrate (kbps) | 70.8 | 59.7 | 113.4 | 104.6 | 275.6 | 258.9 | 500.1 | 570.1 |
Rate–quality ladder (same three-clip mean)
| Codec | Resolution | Bitrate (kbps) | Encode path (ms) | LPIPS (↓) | PSNR (dB) | MPJPE (px, ↓) | Hands vs GT (%, ↑) |
|---|---|---|---|---|---|---|---|
| Reference HEVC | 1080p | 4,200 | — | 0.000 | ∞ | 0.0 | 100 |
| PointStream | 240p bg | 70.8 | 18.4 | 0.320 | 20.96 | 77.5 | 50.3 |
| AV1 p7 | 180p | 48.3 | 18.4 | 0.400 | 20.78 | — | — |
| AV1 p7 | 240p | 59.7 | 10.3 | 0.300 | 21.69 | 81.1 | 51.8 |
| PointStream | 360p bg | 113.4 | 18.4 | 0.210 | 22.11 | 65.8 | 53.3 |
| AV1 p7 | 360p | 104.6 | 11.7 | 0.197 | 23.04 | 74.2 | 57.0 |
| PointStream | 540p bg | 275.6 | 18.4 | 0.127 | 23.69 | 64.6 | 53.1 |
| AV1 p7 | 540p | 263.5 | 3.3 | 0.118 | 24.95 | 62.8 | 66.1 |
| PointStream | 1080p bg | 500.1 | 18.4 | 0.076 | 25.04 | 74.3 | 56.8 |
| AV1 p6 | 1080p | 570.1 | 3.3 | 0.061 | 27.46 | 48.8 | 72.7 |
Rate-Distortion Pareto Curves & Latency Profile
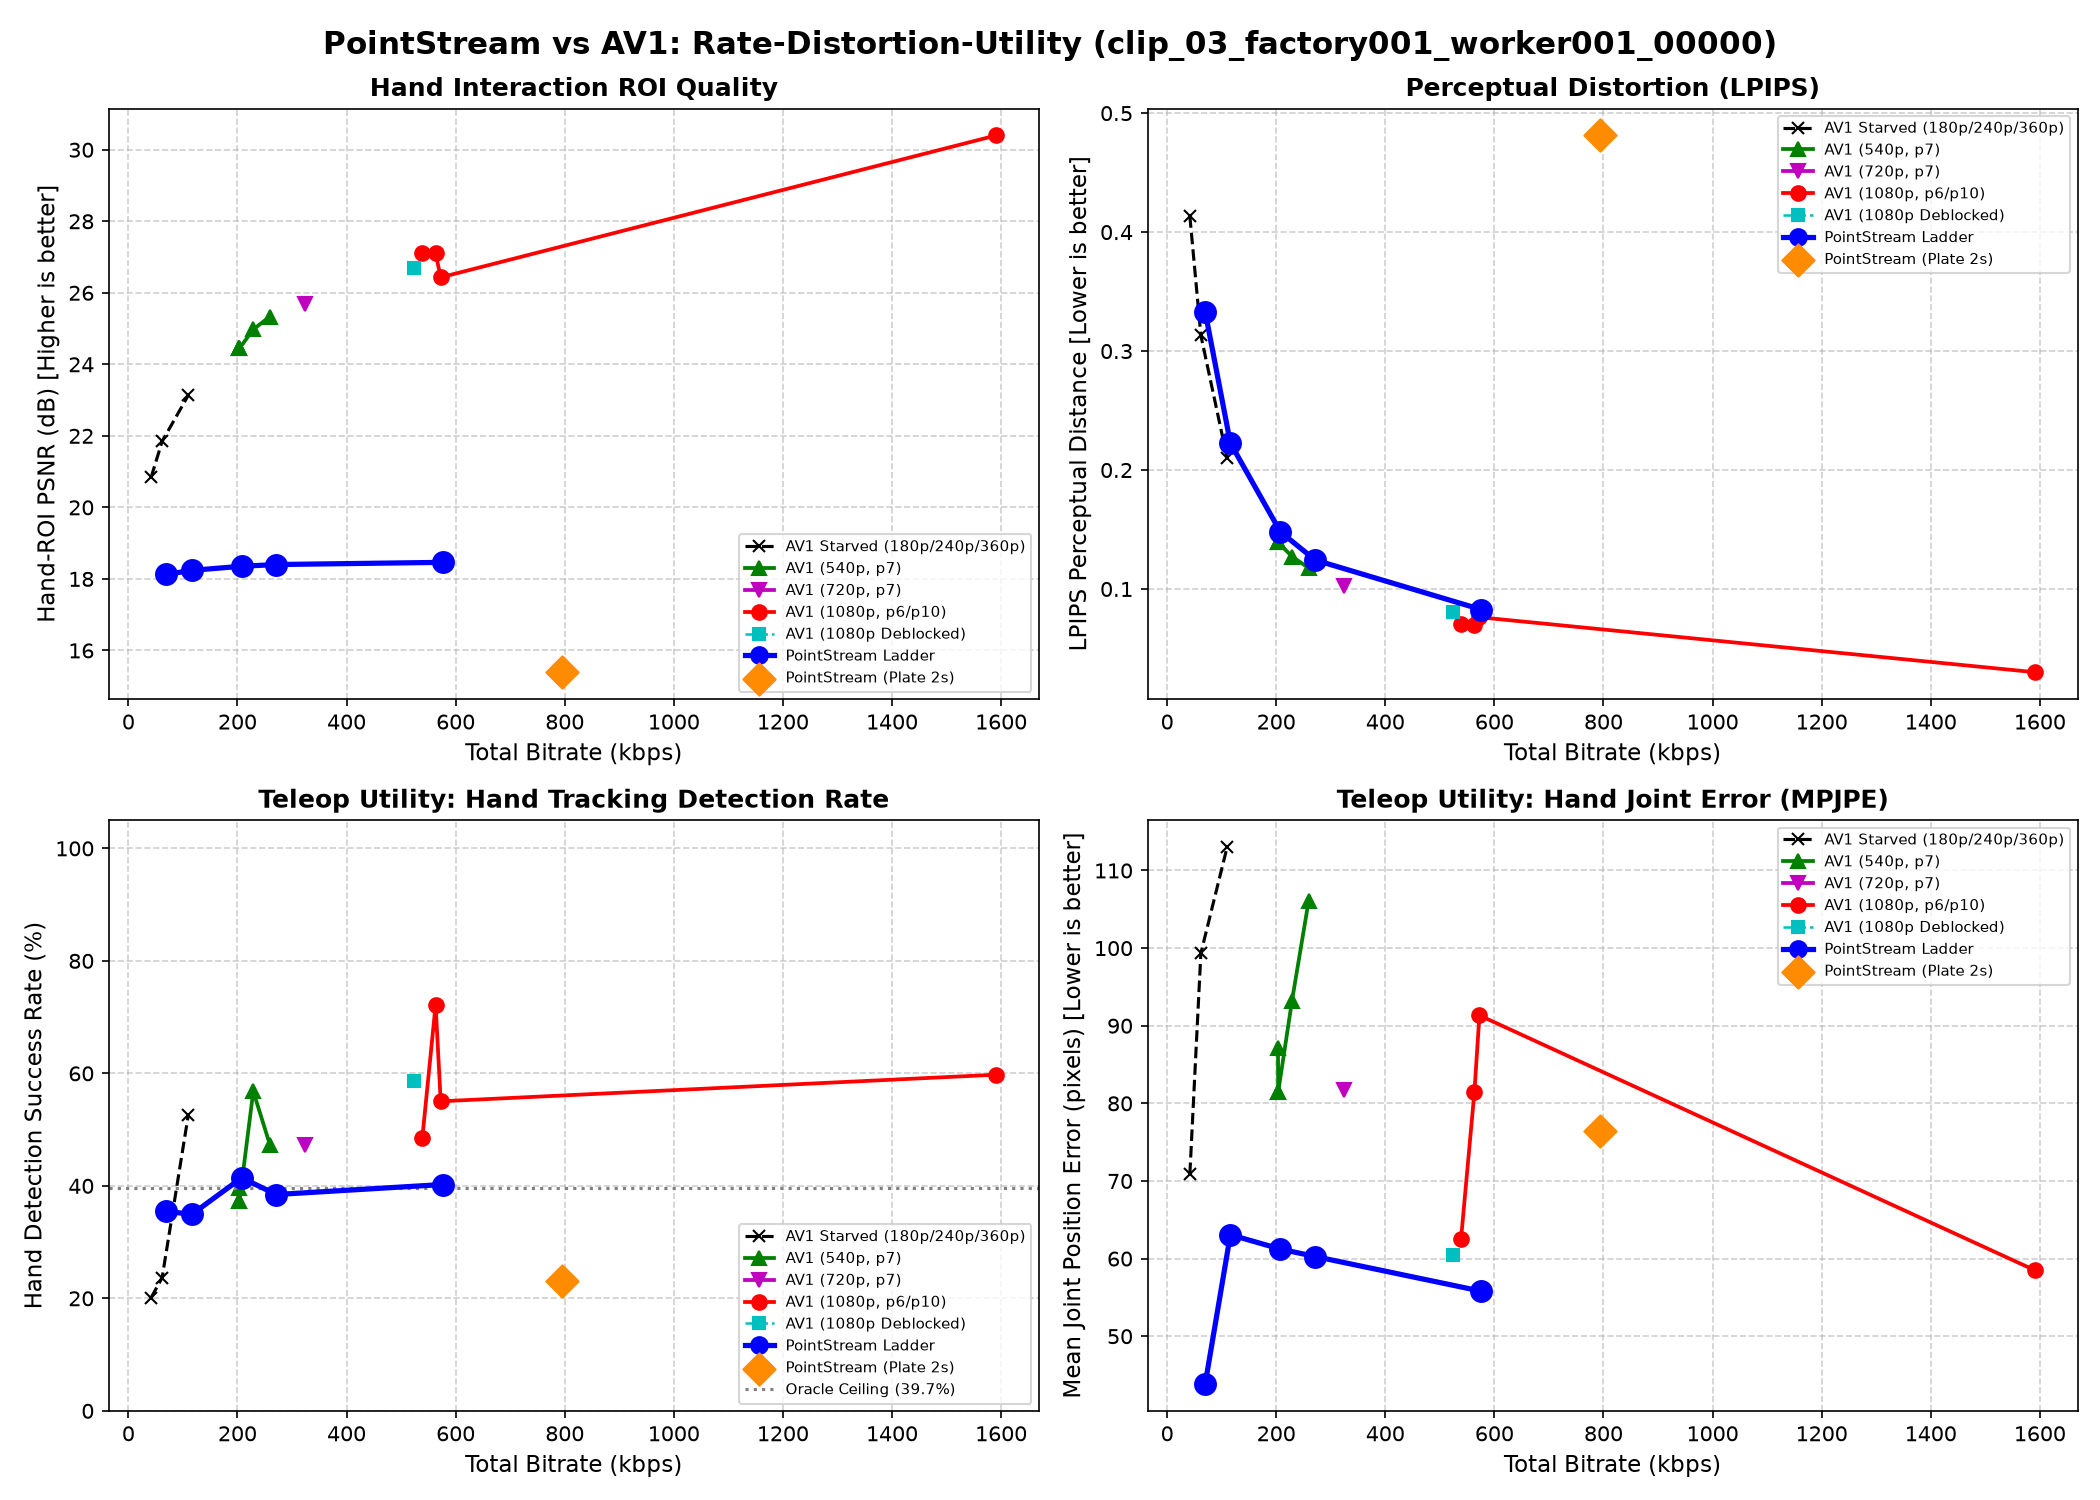
Pareto curves for the clip on screen. New windows: close hands (factory 35), slow assembly, table work. Three-clip starve mean: PS 89.1 px / 49.5% vs AV1 81.1 px / 51.8%.
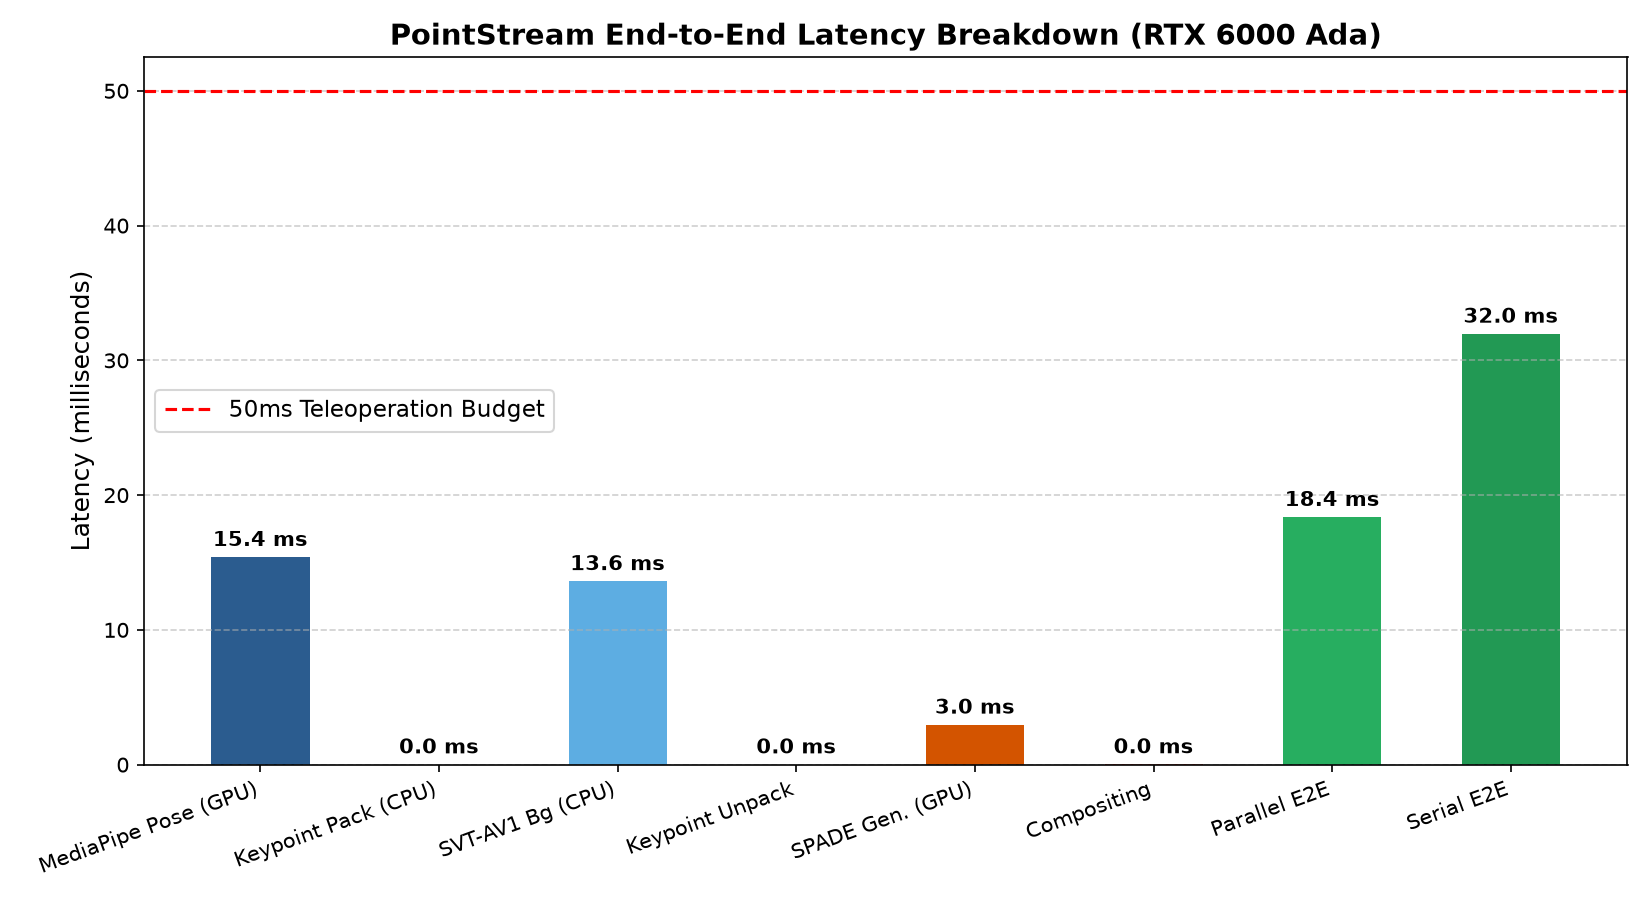
PointStream latency on NVIDIA RTX 6000 Ada. Pose extraction 15.4 ms overlaps SVT-AV1 13.6 ms; parallel E2E 18.4 ms, serial 32.0 ms.
System Architecture: Asynchronous Semantic Decomposition
[Robot Camera / Head Node]
  ├── MediaPipe Hand Pose (GPU: 15.4 ms) ──> 1-Euro Smoothing ──> Quantizer (47 B/hand) ──> [Keypoint Stream: 7-10 kbps]
  └── Scale + SVT-AV1 (240p–1080p bg)    ──> Lanczos up to 1080p (CPU: 13.6 ms)        ──> [Background Stream: 59-264 kbps]
                                                                                                │
                                                                                  Total Stream: 70-276 kbps (15x-60x) + shared WebP anchors 3.77 kbps
                                                                                                │
[Teleop Station / Policy Ingestion Node]                                                        ▼
  ├── Unpack Keypoints (<0.01 ms) ──> Render Wireframe Skeleton Canvas
  ├── Appearance Anchor Crop       ──> Lightweight Generator (GPU: 2.95 ms) ──> Synthesized Hands
  └── Decode Background Stream     ──────────────────────────────────────────┴─> Composited Frame (0.01 ms)
Decoupled Interaction Architecture (Modes 2 & 3)
To ensure active performance optimization sessions (TensorRT, CUDA fusion, batching) do not break the interactive application, the system exposes a stable StreamingCodecAdapter contract:
class StreamingCodecAdapter(Protocol):
    def configure(self, width: int, height: int, target_kbps: int) -> None: ...
    def process_frame(self, frame_bgr: np.ndarray) -> FrameResult: ...
Mode 2: Dynamic Video Selection & Server Processing
Allows users to select or drag-and-drop arbitrary egocentric videos. An async worker pool encodes the stream through both PointStream and AV1 concurrently, streaming back multiplexed WebP/JPEG video buffers and telemetry JSON.
Mode 3: Live Camera Teleoperation (Hand Motion via Webcam)
Captures real-time camera frames via navigator.mediaDevices.getUserMedia(). Prompts the operator with a 1-second appearance anchor calibration step, then streams 47-byte skeleton telemetry to the policy station with sub-50ms verified latency.
Production Deployment Path to emanueleartioli.com
- Stage 1 (Current): Static zero-dependency deployment on
emanueleartioli.com/ GitHub Pages with 60fps canvas slicing. - Stage 2: Hosted GPU worker backend on an on-demand VPS / serverless container for dynamic uploads.
- Stage 3: Client-side edge inference via ONNX Runtime Web / WebGPU, running neural synthesis directly on the visitor's local GPU without server costs.